
Abstract
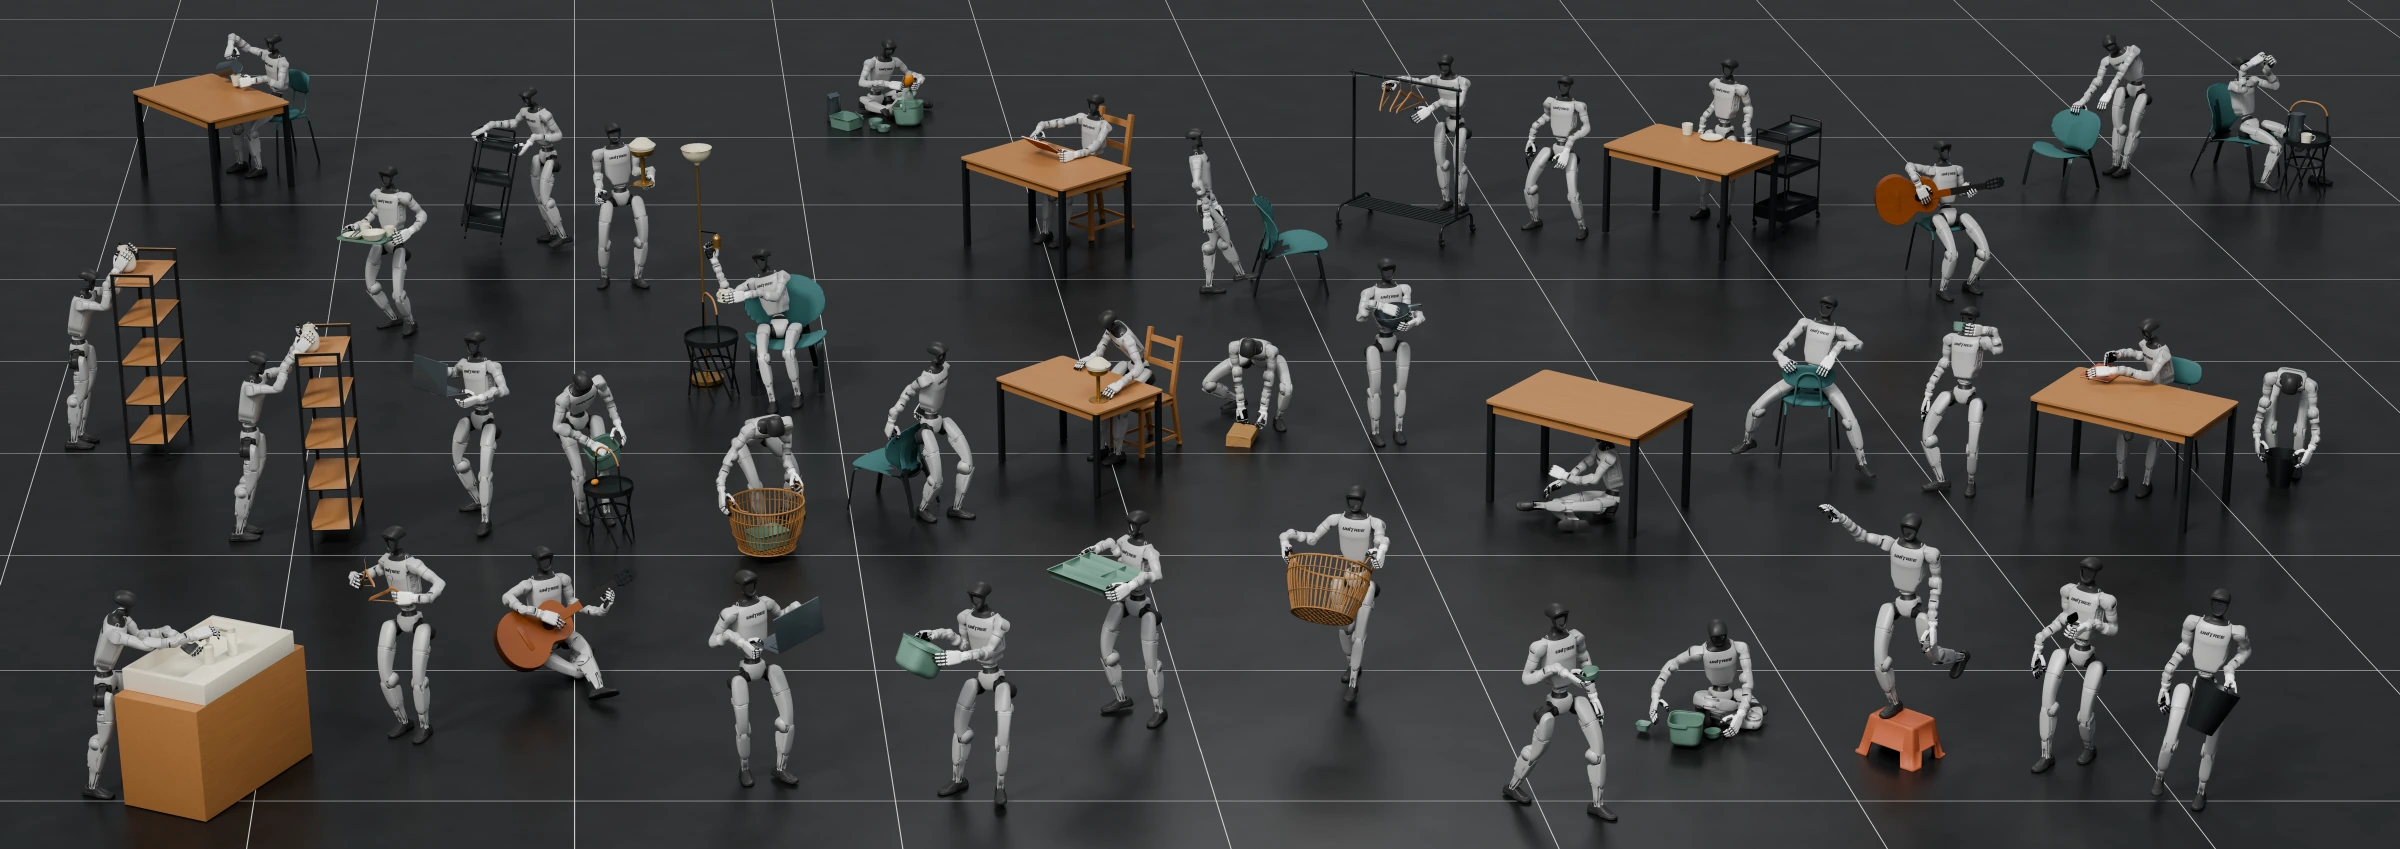
Learning dexterous humanoid loco-manipulation from human demonstrations requires transferring not only human motion, but also the coordinated interaction structure underlying the demonstrated behavior. This is challenging because embodiment differences distort the coupling among body motion, wrist placement, finger articulation, and object interaction, while kinematically accurate references may still be difficult to realize under robot dynamics. We present DexWeave, a unified framework that connects interaction-consistent motion retargeting with anatomy-aware whole-body policy learning. DexWeave first employs a two-stage retargeting procedure that initializes body and hand motions with specialized solvers and subsequently performs coupled refinement over the upper-body interaction chain while preserving lower-body support. The resulting references are tracked by an anatomy-aware Transformer policy that represents anatomical regions as structured tokens and uses directed masked attention to model their dependencies, with object information selectively conditioning the upper-body pathway for dexterous interaction. The policy jointly outputs body and dexterous-hand actions and is trained directly with reinforcement learning, without pretrained tracking policies, teacher–student distillation, or subsequent residual refinement. Across multiple dexterous loco-manipulation motions, DexWeave improves retargeting fidelity and interaction consistency while achieving higher manipulation performance and faster policy convergence than MLP baselines. We further deploy the learned policies on a physical Unitree G1 humanoid equipped with Inspire dexterous hands, demonstrating dexterous whole-body loco-manipulation in the real world.
Method overview
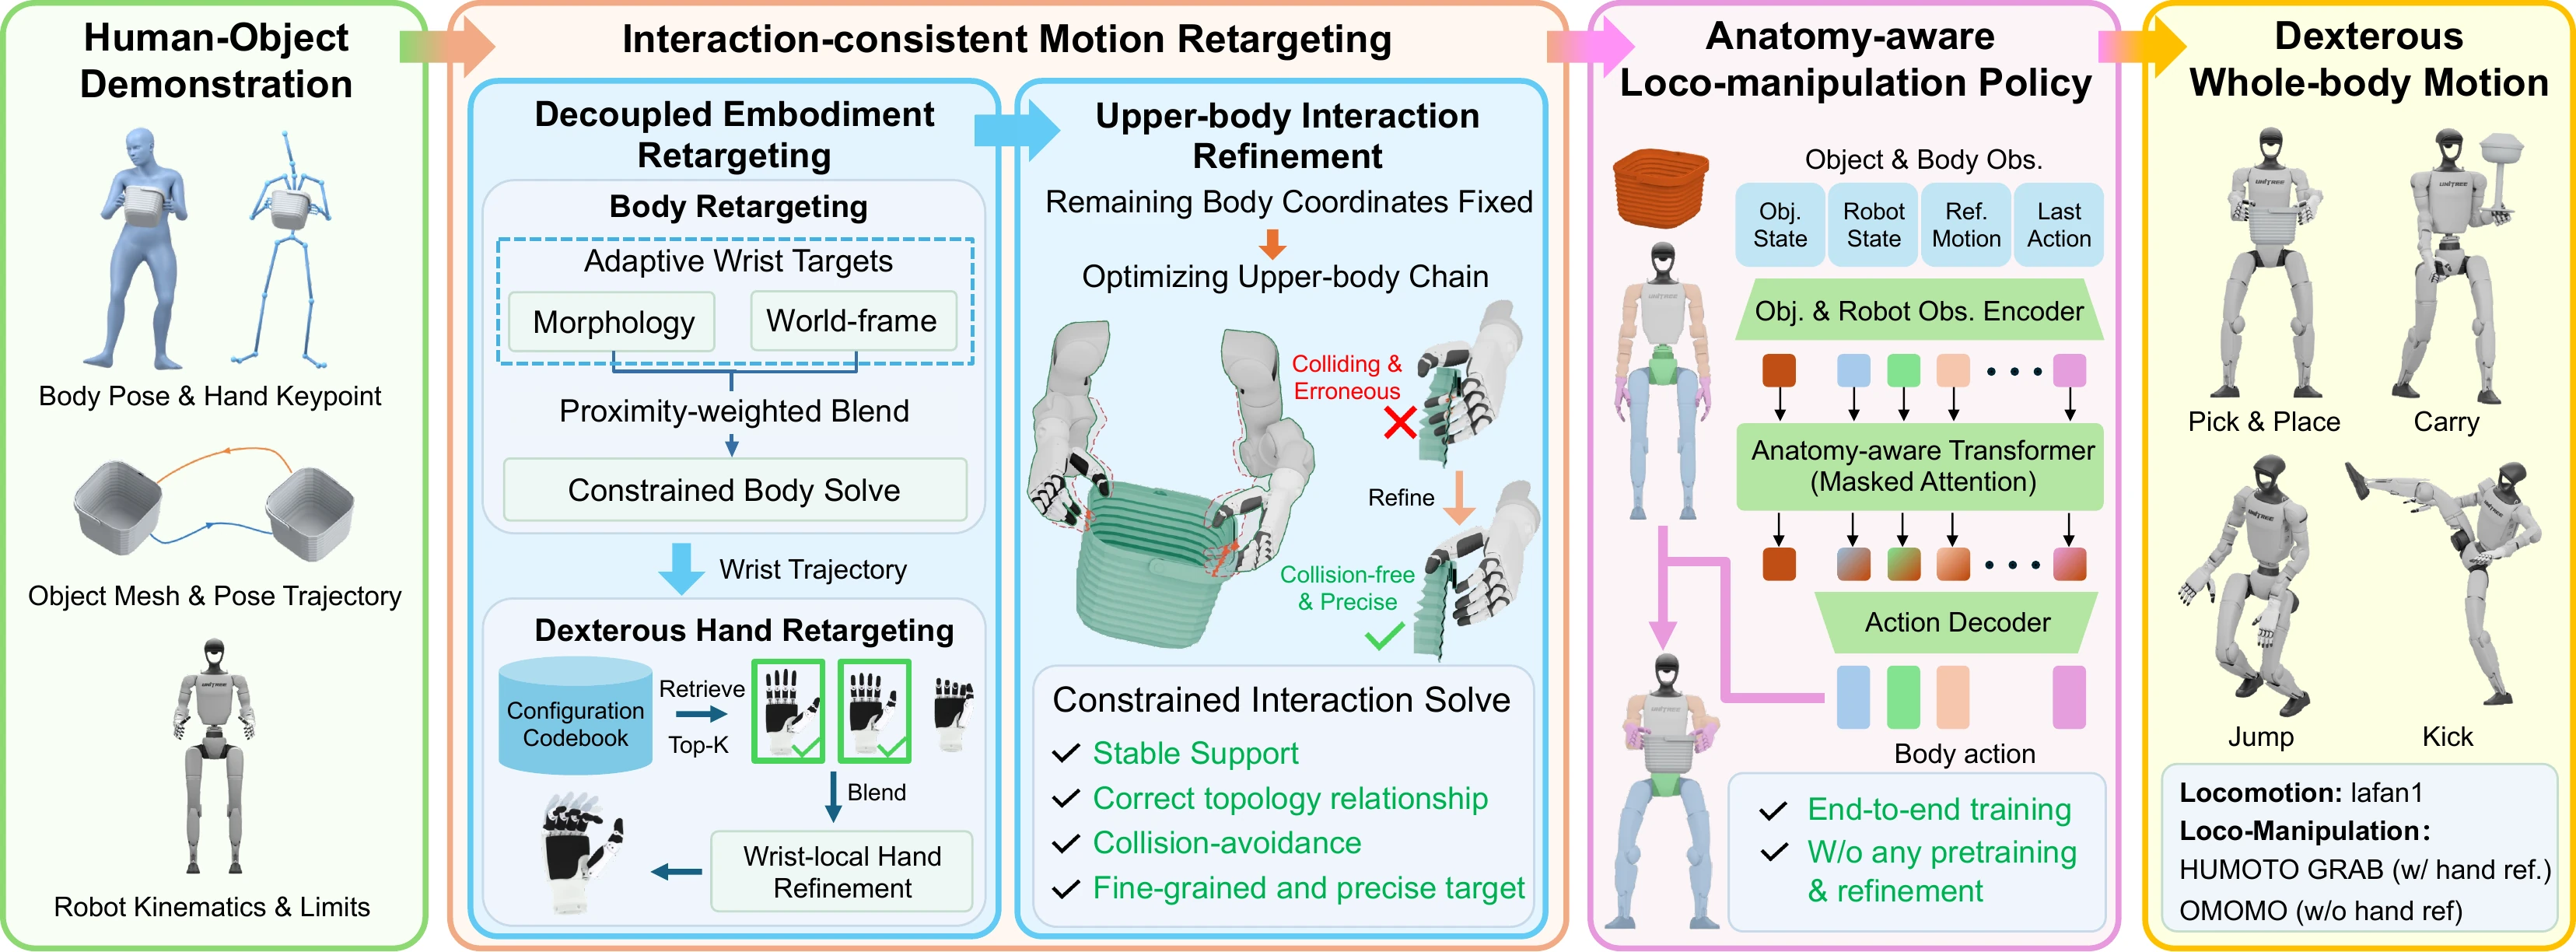
Given a human body–hand–object demonstration, DexWeave first constructs an interaction-consistent robot reference through specialized body–hand initialization and coupled refinement of the upper-body interaction chain. An anatomy-aware whole-body loco-manipulation policy then realizes the reference under robot dynamics using regional anatomical tokens, directed masked attention, and selective object conditioning, producing executable dexterous humanoid loco-manipulation skills.
Real-world experiments
Loco-Manipulation


Locomotion


Retargeting results
Video results
Loco-Manipulation from HUMOTO Dataset

Carrying a serving bowl

Turning on a floor lamp

Taking selfies

Mug and plate transfer

Carrying an organizer tray

Grasping a notebook

Lifting and tilting a table

Drinking and reading

Organizing kitchenware

Dropping and picking up a spoon

Cooking with a wok turner

Picking up a woven basket

Walking with a laptop

Emptying a wash tub

Moving a dining chair

Plate and mug transfer
Locomotion from LAFAN1 Dataset

fightAndSports1_subject1

pushAndFall1_subject1

dance1_subject3

run2_subject1

ground1_subject5

pushAndStumble1_subject2

aiming2_subject3

jumps1_subject5
Quantitative results
| Dataset | Method | Penetration | Foot skating | Contact preservation | |||
|---|---|---|---|---|---|---|---|
| Duration ↓ | Max. depth (cm) ↓ | Duration ↓ | Max. velocity (m/s) ↓ | Duration ↑ | Contact distance (cm) ↓ | ||
| LAFAN1 | OmniRetarget | 0.125 | 2.934 | 0.091 | 0.416 | N/A | N/A |
| GMR | 0.183 | 4.314 | 0.010 | 0.548 | N/A | N/A | |
| SOMA | 0.968 | 6.379 | 0.115 | 0.565 | N/A | N/A | |
| DexWeave (Ours) | ≈0 | 2.575 | 0 | 0 | N/A | N/A | |
| OMOMO | OmniRetarget | 0.131 | 2.735 | ≈0 | 1.455 | 0.644 | 10.289 |
| GMR | 0.916 | 3.117 | 0.008 | 0.802 | 0.879 | 7.677 | |
| SOMA | 0.746 | 4.163 | 0.034 | 0.467 | 0.577 | 16.205 | |
| DexWeave (Ours) | 0.002 | 2.117 | ≈0 | 0.355 | 0.999 | 2.944 | |
Bold marks the best value and underlining the second-best within each dataset. Durations are frame fractions; ≈0 denotes a near-zero value.
| Dataset | Method | Penetration | Hand alignment | |||
|---|---|---|---|---|---|---|
| Duration ↓ | Max. depth (cm) ↓ | Primary error (mm) ↓ | Secondary error (mm) ↓ | Palm error (°) ↓ | ||
| GRAB | OmniRetarget + DexPilot + IK | 0.212 | 2.269 | 16.585 | 13.368 | 11.555 |
| OmniRetarget + SBR + IK | 0.190 | 2.362 | 14.925 | 14.659 | 9.530 | |
| DexWeave (Ours) | 0.001 | 1.263 | 4.342 | 14.476 | 3.652 | |
| HUMOTO | OmniRetarget + DexPilot + IK | 0.522 | 3.597 | 32.389 | 31.018 | 14.444 |
| OmniRetarget + SBR + IK | 0.511 | 3.582 | 29.999 | 28.436 | 12.476 | |
| DexWeave (Ours) | 0.007 | 2.854 | 7.198 | 11.702 | 4.439 | |
Bold marks the best value and underlining the second-best within each dataset. Primary: thumb and index fingertips. Secondary: remaining fingertips. Palm: palm-normal angular error.
Sim-to-Sim results
Deploy an IsaacLab-trained policy in MuJoCo
Loco-Manipulation from HUMOTO Dataset

Moving a vase between shelves

Lifting a basket

Pouring from a mug

Lifting a table lamp

Walking with a mixing bowl

Transferring basket from cart to table

Moving a bowl by its handle

Walking with a woven basket

Moving and shaking a bowl

Lifting and lowering a bin

Moving a chair

Stepping onto a stool
Locomotion from LAFAN1 Dataset

Running

Dancing

Shadowboxing

Mixed movements

Jumping

Hopping
| Method | Completion ratio (%) ↑ | Body-position error (cm) ↓ | Anchor-position error (cm) ↓ | Anchor-rotation error (deg) ↓ |
|---|---|---|---|---|
| Any2Track | 72.82 | 6.09 | 44.88 | 32.07 |
| GMT | 69.86 | 5.85 | 36.06 | 21.92 |
| BeyondMimic | 100 | 2.82 | 5.19 | 2.48 |
| DexWeave (Ours) | 100 | 2.62 | 4.82 | 2.34 |
MuJoCo sim-to-sim evaluation, averaged equally over five tracking motions. DexWeave trains a separate policy for each reference sequence; Any2Track and GMT are included as general motion-tracking baselines. Completion ratio is the percentage of evaluation episodes reaching the reference end or time limit. Best values are in bold.
| Method | Success rate (%) ↑ | Body-position error (cm) ↓ | Object-position error (cm) ↓ | Object-rotation error (deg) ↓ |
|---|---|---|---|---|
| InterMimic | 57.74 | 6.51 | 3.58 | 7.71 |
| Object MLP | 85.00 | 5.69 | 3.84 | 6.16 |
| DexWeave (Ours) | 97.5 | 4.93 | 3.43 | 6.83 |
MuJoCo sim-to-sim evaluation, averaged equally over five loco-manipulation references. InterMimic is trained and evaluated using the SMPL model. Best values are in bold.
Citation
@article{sun2026dexweave,
  author  = {Sun, Naichuan and Shen, Haotian and Zhang, Yizhang and Feng, Luying and Wang, Haoze and Xiangli, Yuanbo and Jin, Yaochu and Liu, Peidong},
  title   = {DexWeave: Learning Dexterous Humanoid Loco-Manipulation from Human Demonstrations},
  journal = {arXiv},
  year    = {2026},
}